Welcome to Week 2#
Last week, you learned how to build distributed systems—partitioning data, replicating for availability, protecting against overload, and handling skewed traffic. You built a session store for 10 million users.
This week, we assume everything you built will fail.
Networks will drop packets. Services will crash mid-request. Databases will timeout. Users will click buttons twice. And when failures cascade, your entire system can collapse in seconds.
Week 2 teaches you to design systems where failure is the normal case, not the exception.
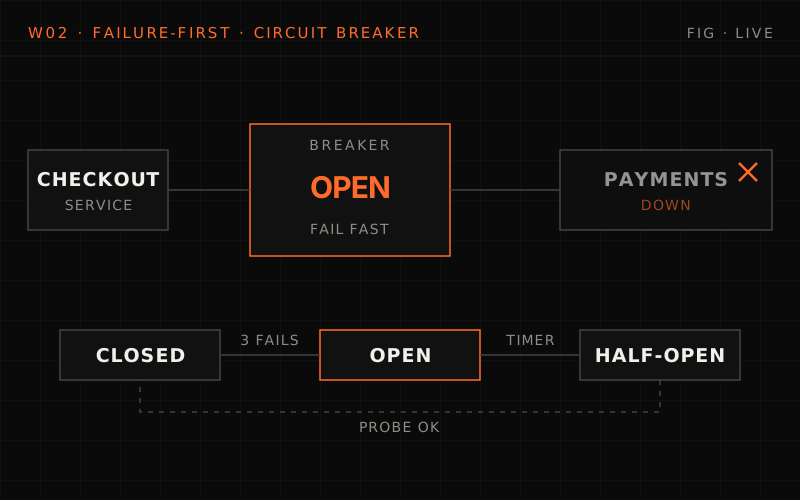
Week 2 assumes everything you built will fail, and asks how it fails before how it works, focusing on omission and timing failures. It covers timeout budgets, retries with backoff and jitter, idempotency keys, circuit breakers (closed, open, half-open), at-least-once delivery with idempotent receivers, and leader election, applied to three systems: a payment pipeline (days 1 to 3), webhook delivery at 1M an hour, and a distributed job scheduler. The pitfalls: just retrying, long timeouts, treating an open breaker as an outage, and assuming exactly-once is simple.
The Week at a Glance#
| Day | Topic | Core Question |
|---|---|---|
| 1 | Timeout Hell | How do you set timeouts when you call 3 services, each with different latency? |
| 2 | Idempotency in Practice | User clicks "Pay" twice—did you charge them twice? |
| 3 | Circuit Breakers | Your payment provider is down—do you fail fast or retry forever? |
| 4 | Webhook Delivery | Receiver is down for 2 hours—how do you guarantee delivery? |
| 5 | Distributed Cron | Leader dies mid-job—does the job run twice, once, or never? |
Week 2 Theme: Designing for Failure#
The Mindset Shift#
Week 1 thinking "How do I make this system work?"
Week 2 thinking "How does this system fail, and what happens when it does?"
Every design decision this week starts with the failure case:
- Before choosing a timeout: "What happens when this times out?"
- Before adding a retry: "What if the first request actually succeeded?"
- Before implementing a circuit breaker: "What's the user experience when the circuit opens?"
Why This Matters#
The systems that survive at scale are not the ones that never fail—they're the ones that fail gracefully. Consider these real-world incidents:
- Amazon (2017): A us-east-1 S3 outage took down large parts of the web because many services had no fallback for "S3 unavailable"
- Knight Capital (2012): A botched deploy reactivated dead trading code + no kill switch = $460 million loss in 45 minutes
- Stripe: Processes billions in payments and lets clients send an idempotency key on every write—a retried or double-clicked request never double-charges
This week, you'll learn the patterns that make the difference.
Week 2 warm-up
Q1/2 A call to the bank API times out, and your code is about to retry it automatically. What is the failure-first question to ask before retrying?
Answer & explanation
Answer: B
A timeout does not mean failure; the bank may have charged the card. Retrying blindly can double-charge. Timeout length matters too, but it does not answer whether the first attempt went through.
Q2/2 A user double-clicks "Pay". Which property lets a system like Stripe guarantee they are charged only once?
Answer & explanation
Answer: A
Making every operation idempotent means the second click is recognized and returns the first result instead of charging again. Circuit breakers and timeouts handle slow or failing dependencies, not duplicate requests.
The Three Systems You'll Design#
System 1: Payment Processing Pipeline (Days 1-3)#
The highest-stakes system in most companies. A bug here means real money lost, double charges, or failed transactions.
%% title: Payment processing pipeline
flowchart TD
  U@{ icon: "sd:user", label: "User clicks<br/>“Pay $99”" } --> F@{ icon: "sd:shield", label: "Fraud Check<br/>200ms" }
  F --> B@{ icon: "sd:bank", label: "Bank API<br/>2000ms" }
  B --> N@{ icon: "sd:bell", label: "Notify Service<br/>100ms" }
  N --> D(["Done"]):::ok
  class U client
  class F,N service
  class B external
What can go wrong?
- Fraud check times out
- Bank API returns "maybe" (network died mid-response)
- User clicks Pay again while waiting
- Notification fails—does payment fail too?
- Bank API is degraded on Black Friday
Day 1 Set timeouts correctly. Handle the "bank is slow today" scenario.
Day 2 Make it idempotent. Handle the "user clicked twice" scenario.
Day 3 Add circuit breakers. Handle the "bank is down on Black Friday" scenario.
System 2: Webhook Delivery System (Day 4)#
Deliver events reliably to external systems that you don't control.
%% title: Webhook delivery system
flowchart TD
  Q@{ icon: "sd:queue", label: "Queue<br/>Events: order.created ·<br/>payment.success · refund.issued" }
  subgraph CE["Customer Endpoints"]
    direction TB
    C1@{ icon: "sd:webhook", label: "https://customer1/wh" }
    C2@{ icon: "sd:webhook", label: "https://customer2/wh" }
    C3@{ icon: "sd:webhook", label: "https://customer3/wh (down)" }
  end
  Q --> CE
  Q --> DLQ@{ icon: "sd:queue", label: "DLQ (Dead Letter)<br/>“Customer 3 has failed 50 times”<br/>“Oldest undelivered: 2 hours ago”" }
  class Q,DLQ queue
  class C1,C2 external
  class C3 bad
Challenges:
- Customer endpoint is slow (10s response time)
- Customer endpoint is down for maintenance
- Customer endpoint returns 200 but didn't process
- Same event delivered twice—customer must handle it
- 1M webhooks/hour throughput requirement
Goal: Guarantee at-least-once delivery with clear visibility into failures.
System 3: Distributed Cron / Job Scheduler (Day 5)#
Run scheduled jobs exactly once, even when servers crash mid-execution.
%% title: Distributed job scheduler
flowchart TD
  subgraph SN["Scheduler Nodes"]
    direction TB
    N1["Node 1<br/>(Leader)"]:::core
    N2@{ icon: "sd:server", label: "Node 2<br/>(Follower)" }
    N3@{ icon: "sd:server", label: "Node 3<br/>(Follower)" }
  end
  subgraph WP["Worker Pool"]
    direction TB
    W1["Worker 1: Running<br/>daily_digest (50%)"]:::hot
    W2@{ icon: "sd:worker", label: "Worker 2: Idle" }
    W3@{ icon: "sd:worker", label: "Worker 3: Idle" }
  end
  N1 -->|"9:00 AM — trigger daily_digest job"| WP
  class N2,N3,W2,W3 service
Jobs:
- "Send daily digest" — every day at 9am
- "Generate reports" — every hour
- "Cleanup expired sessions" — every 15 minutes
Failure scenarios:
- Leader dies before triggering 9am job — job missed?
- Leader dies after triggering but before marking complete — runs 2x?
- Worker dies mid-job — restart from scratch or resume?
- Clock skew between nodes — job triggers at wrong time?
- Deploy happens at 9am — job runs on both old and new version?
Goal: Jobs run exactly once, on schedule, even through failures and deployments.
Key Concepts for Week 2#
Concept 1: Failure Modes#
Not all failures are the same. Understanding the type of failure changes your response.
| Failure Mode | Description | Example | How to Handle |
|---|---|---|---|
| Crash | Process dies suddenly | OOM kill, hardware failure | Restart, failover |
| Omission | Message lost, no response | Network partition, packet drop | Timeout + retry |
| Timing | Response too slow | Overloaded service, GC pause | Timeout + fallback |
| Byzantine | Incorrect behavior | Bug, data corruption | Harder—validation, checksums |
This week focuses on Omission and Timing failures—the most common in distributed systems.
Concept 2: Timeouts#
Timeouts seem simple until you have to choose actual numbers.
Your service has 5 seconds to respond to users. You call:
- Service A: P99 = 200ms
- Service B: P99 = 500ms
- Service C: P99 = 100ms
Question: What timeouts do you set?
Bad answer: "5 seconds for each"
→ If A is slow, you have no time left for B and C
Bad answer: "Use their P99 as timeout"
→ P99 means 1% of requests are slower—you'll time out ~1% of calls to each service even when it's healthy
Good answer: "Timeout budget with headroom"
- → Total budget: 4.5s (leave 500ms buffer)
- → A: 500ms (2.5x P99), B: 2s (4x P99), C: 300ms (3x P99)
- → Parallel where possible to save time
Day 1 deep-dives into timeout strategies, cascading failures, and adaptive timeouts.
Concept 3: Retry Strategies#
Retrying failed requests seems helpful, but naive retries cause stampedes.
- 10:00:00.000 — Request fails
- 10:00:00.001 — Server 1 retries
- 10:00:00.001 — Server 2 retries
- 10:00:00.001 — Server 3 retries
- ... — (30 requests hit at once)
- Result — This multiplies load up to 4x (1 original + 3 retries per request) and can take down an already struggling service.
Retry best practices:
- Exponential backoff: Wait longer between each retry
- Jitter: Add randomness so retries don't synchronize
- Retry budgets: Limit total retries across all clients
- Idempotency: Ensure retries don't cause duplicate effects
Concept 4: Idempotency#
An operation is idempotent if performing it multiple times has the same effect as performing it once.
Idempotent
DELETE /users/123— Deleting twice = user still deletedPUT /users/123 {"name": "Alice"}— Setting twice = name is Alice
NOT Idempotent
POST /orders— Creating twice = two ordersPOST /payments— Paying twice = charged twice!
Making non-idempotent operations idempotent:
# Client sends idempotency key
POST /payments
Idempotency-Key: user123-order456-attempt1
{amount: 99.00}

# Server logic:
if idempotency_key in processed_requests:
    return cached_response  # Don't charge again
else:
    process_payment()
    cache_response(idempotency_key, response)
    return response
Day 2 covers idempotency key strategies, deduplication windows, and edge cases.
Concept 5: Circuit Breakers#
A circuit breaker stops calling a failing service to prevent cascade failures.
%% title: Circuit breaker states
stateDiagram-v2
  direction LR
  [*] --> CLOSED
  CLOSED: CLOSED (normal)
  OPEN: OPEN (failing)
  HALF_OPEN: HALF-OPEN (testing)
  CLOSED --> CLOSED: success
  CLOSED --> OPEN: failures > threshold
  OPEN --> HALF_OPEN: timeout
  HALF_OPEN --> CLOSED: success
  HALF_OPEN --> OPEN: failure
  class CLOSED ok
  class OPEN bad
  class HALF_OPEN queue
- CLOSED: Normal operation, requests flow through
- OPEN: Fail immediately, don't call downstream service
- HALF-OPEN: Allow one request through to test if service recovered
When circuit breakers help Prevent cascade failures, fail fast, give struggling services time to recover.
When they hurt Open circuit during legitimate traffic spike, block all users when only some requests fail.
Day 3 covers circuit breaker implementation, tuning, and alternatives.
Concept 6: Delivery Guarantees#
When delivering messages, you can choose your guarantee:
| Guarantee | Meaning | Implementation |
|---|---|---|
| At-most-once | Message may be lost, never duplicated | Fire and forget |
| At-least-once | Message delivered 1+ times, may duplicate | Retry until ACK |
| Exactly-once | Message delivered exactly once | At-least-once + idempotency |
The truth about exactly-once: It's impossible in distributed systems without receiver cooperation. What we actually implement is "at-least-once delivery with idempotent receivers."
Day 4 covers how to build reliable webhook delivery with these guarantees.
Concept 7: Leader Election#
When multiple nodes could do a job, how do you ensure only one does it?
Without leader election
- Node 1: "It's 9 AM, run daily_digest"
- Node 2: "It's 9 AM, run daily_digest"
- Node 3: "It's 9 AM, run daily_digest"
→ Job runs 3 times!
With leader election
- Node 1 (Leader): "It's 9 AM, run daily_digest"
- Node 2 (Follower): "Node 1 is leader, I'll wait"
- Node 3 (Follower): "Node 1 is leader, I'll wait"
→ Job runs once
Leader election mechanisms:
- Consensus algorithms (Raft, Paxos)
- Lease-based (acquire lock with TTL)
- External coordinator (ZooKeeper, etcd, Redis)
Day 5 covers leader election, fencing tokens, and building reliable schedulers.
Daily Breakdown#
Day 1: Timeout Hell#
Morning Concept (10 min)#
- Timeout budgets: Dividing time across dependent services
- Cascading timeout failures: How one slow service takes down everything
- Adaptive timeouts: Adjusting based on observed latency
Design Challenge (35 min)#
Design a payment service calling:
- Fraud check (P99 = 200ms)
- Bank API (P99 = 2s)
- Notification service (P99 = 100ms)
Challenge questions:
- What timeout do you set for each service?
- Bank API is slow today (P99 = 5s)—what happens to your users?
- How do you prevent notification failure from failing the whole payment?
Discussion (15 min)#
- Would you use adaptive timeouts? What's the risk?
- How do you detect a slow downstream before users notice?
- What's the difference between timeout and deadline propagation?
Day 2: Idempotency in Practice#
Morning Concept (10 min)#
- Idempotency key strategies: Client-generated vs server-generated
- Deduplication windows: How long to remember processed requests
- The "network timeout" problem: Request succeeded but client doesn't know
Design Challenge (35 min)#
Design payment retry logic for the system from Day 1.
Challenge scenario:
- User clicks "Pay $99"
- Request sent to your server
- Your server calls bank API
- Network timeout—did the bank charge or not?
- User clicks "Pay" again
Design the system so the user is never charged twice.
Discussion (15 min)#
- Where do you store idempotency keys? (Redis? Database?)
- What's the right TTL for idempotency records?
- How do you handle idempotency key collisions?
Day 3: Circuit Breakers#
Morning Concept (10 min)#
- Circuit breaker states: Closed, Open, Half-Open
- Failure detection: Count-based vs time-based
- When circuit breakers cause harm
Design Challenge (35 min)#
Add circuit breakers to your payment system.
Challenge scenario: It's Black Friday. Bank API is degraded (50% of requests failing, P99 = 10s).
- Circuit breaker opens after 10 failures
- 1000 customers are trying to pay right now
Questions:
- What's the customer experience when the circuit opens?
- How do you communicate "try again later" vs "payment failed"?
- Should you have different circuit breaker settings for different times?
Discussion (15 min)#
- Circuit breaker vs retry with backoff vs bulkhead: When each?
- How do you test circuit breakers in production?
- What metrics do you monitor for circuit breaker health?
Day 4: Webhook Delivery#
Morning Concept (10 min)#
- Delivery guarantees: At-most-once, at-least-once, exactly-once
- Why receivers must be idempotent
- Webhook security: Signatures, replay attacks
Design Challenge (35 min)#
Design a webhook system delivering 1M webhooks/hour.
Challenge scenario: Customer's endpoint is down for 2 hours.
- How many retries?
- What backoff strategy?
- When do you give up and put in dead letter queue?
- How does the customer know they missed webhooks?
Discussion (15 min)#
- Design the dead letter queue and manual retry interface
- How do you handle slow receivers (10s response time)?
- What's your strategy for a receiver that returns 200 but doesn't process?
Day 5: Distributed Cron#
Morning Concept (10 min)#
- Leader election basics: Why it's needed, how it works
- Fencing tokens: Preventing "zombie leaders" from causing duplicate runs
- Why ZooKeeper/etcd exist
Design Challenge (35 min)#
Design a job scheduler where jobs run exactly once, even during deploys.
Challenge scenario: Leader dies mid-job.
- Does the job restart from the beginning?
- Does it resume where it left off?
- How do you prevent it from running twice on two different nodes?
Discussion (15 min)#
- Compare to Celery Beat, Kubernetes CronJobs, and Temporal
- How do cloud providers (AWS, GCP) solve this?
- What's the simplest solution that actually works?
Skills You'll Have by Friday#
Technical Skills#
| Skill | You Can Now... |
|---|---|
| Timeout design | Set timeouts for multi-service calls without cascade failures |
| Idempotency | Design payment systems that never double-charge |
| Circuit breakers | Protect systems from downstream failures |
| Webhook delivery | Build reliable at-least-once delivery systems |
| Leader election | Ensure scheduled jobs run exactly once |
Interview Skills#
By the end of Week 2, you'll be able to answer:
- "How do you handle a downstream service that's slow?"
- "How do you prevent duplicate payments?"
- "Design a system to reliably deliver notifications to external systems"
- "How do you ensure a scheduled job runs exactly once?"
- "What happens when [any component] fails?"
Mental Model#
The biggest shift: You'll start every design by asking "What happens when this fails?"
This is the difference between junior and senior system design:
- Junior: "Here's how it works"
- Senior: "Here's how it works, here's how it fails, and here's how we handle that"
Prerequisites Check#
Before starting Week 2, make sure you're comfortable with:
From Week 1#
- Partitioning: You know how data is distributed across nodes
- Replication: You know how data is copied for availability
- Consistency models: You understand eventual vs strong consistency
General Knowledge#
- HTTP basics: Status codes, headers, request/response flow
- Basic queuing: Producer/consumer pattern, message acknowledgment
- Database transactions: ACID properties, commit/rollback
Helpful but Not Required#
- Experience with Redis or similar
- Familiarity with payment systems
- Knowledge of cron syntax
What Makes Week 2 Different#
Week 1 vs Week 2#
| Aspect | Week 1 | Week 2 |
|---|---|---|
| Focus | Data storage and retrieval | Operations that can fail |
| Key question | "Where does data live?" | "What happens when this fails?" |
| Systems | Session store (CRUD-focused) | Payment pipeline (transaction-focused) |
| Main challenge | Scale and distribution | Reliability and correctness |
| Failure handling | "Add replicas" | "Add retries, idempotency, circuit breakers" |
The Payment System Thread#
Days 1-3 build on each other with the same payment system:
%% title: Days 1-3 build on each other
flowchart TD
  D1["Day 1: Build it with<br/>proper timeouts"]:::service --> D2["Day 2: Make it idempotent<br/>(handle double-clicks)"]:::service
  D2 --> D3["Day 3: Add circuit breakers<br/>(handle downstream failures)"]:::service
  D3 --> R(["Result: Production-ready<br/>payment processing pattern"]):::ok
This is how real systems are built—layer by layer, addressing failure modes one at a time.
Common Pitfalls to Avoid#
Pitfall 1: "We'll Just Retry"#
Bad
Retry immediately, 3 times, on any error
- → Amplifies load on struggling services
- → May cause duplicate operations
Good
Exponential backoff with jitter, only on retryable errors
- → Gives services time to recover
- → Idempotency handles duplicates
Pitfall 2: "Long Timeout = Safe"#
Bad
Set 30s timeout "just to be safe"
- → User stares at spinner for 30 seconds
- → Thread pool exhausted waiting
- → Cascade failure when requests pile up
Good
Timeout based on SLA + small buffer
- → Fail fast, show user meaningful error
- → Free resources for other requests
Pitfall 3: "Circuit Breaker Opens = System Down"#
Bad
Circuit opens, return 500 to all users
- → Same experience as if you had no circuit breaker
Good
Circuit opens, use fallback or degraded mode
- → "Payment processing delayed, we'll email confirmation"
- → Partial functionality is better than nothing
Pitfall 4: "Exactly-Once is Simple"#
Bad
Assume exactly-once delivery is a solved problem
- → Build system that breaks with duplicates
- → Production incident on first retry
Good
Build for at-least-once with idempotent receivers
- → Every operation can safely be replayed
- → "Exactly-once" is the emergent behavior
Quick Reference: Week 2 Patterns#
Timeout Budget#
total_budget = 5000  # ms
service_a_timeout = 500   # Allow 10% for critical fast service
service_b_timeout = 3000  # Allow 60% for slow but important service
buffer = 1500             # Reserve 30% for processing + unknowns
Exponential Backoff with Jitter#
def get_retry_delay(attempt: int) -> float:
    base_delay = 0.1  # 100ms
    max_delay = 30.0  # 30 seconds

    exponential = min(base_delay * (2 ** attempt), max_delay)
    jitter = random.uniform(0, exponential * 0.1)

    return exponential + jitter
Idempotency Key Pattern#
def process_payment(idempotency_key: str, amount: float):
    # Simplified: two concurrent duplicates can both pass this check.
    # Day 2 claims the key atomically (SET NX / unique insert) first.
    # Check if already processed
    existing = redis.get(f"idem:{idempotency_key}")
    if existing:
        return json.loads(existing)  # Return cached response

    # Process payment
    result = bank_api.charge(amount)

    # Cache response for future retries (24 hour TTL)
    redis.setex(f"idem:{idempotency_key}", 86400, json.dumps(result))

    return result
Circuit Breaker States#
class CircuitBreaker:
    def call(self, func):
        if self.state == OPEN:
            if time.time() > self.next_attempt_time:
                self.state = HALF_OPEN
            else:
                raise CircuitOpenError()

        try:
            result = func()
            self.record_success()
            return result
        except Exception as e:
            self.record_failure()
            raise
Let's Begin#
Week 2 is about embracing failure as a first-class concern. Every system fails—the question is whether your system fails gracefully or catastrophically.
By Friday, you'll have designed:
- A payment pipeline that handles timeouts, retries, and circuit breakers
- A webhook system that guarantees delivery
- A job scheduler that runs jobs exactly once
You'll think differently about system design. You'll ask "what if this fails?" before "how do I make this work?"
Let's start with Day 1: Timeout Hell.
"Everything fails, all the time." — Werner Vogels, CTO of Amazon
this lesson in shorts · 1
play them all →One idea from this lesson in about a minute each, made for your phone.
New lessons by email
New lessons, side quests and case files as they ship, at most once a week. No spam, unsubscribe anytime.
Discussion · …
Public: everyone reading this lesson sees comments. Be kind and keep it on the material.